
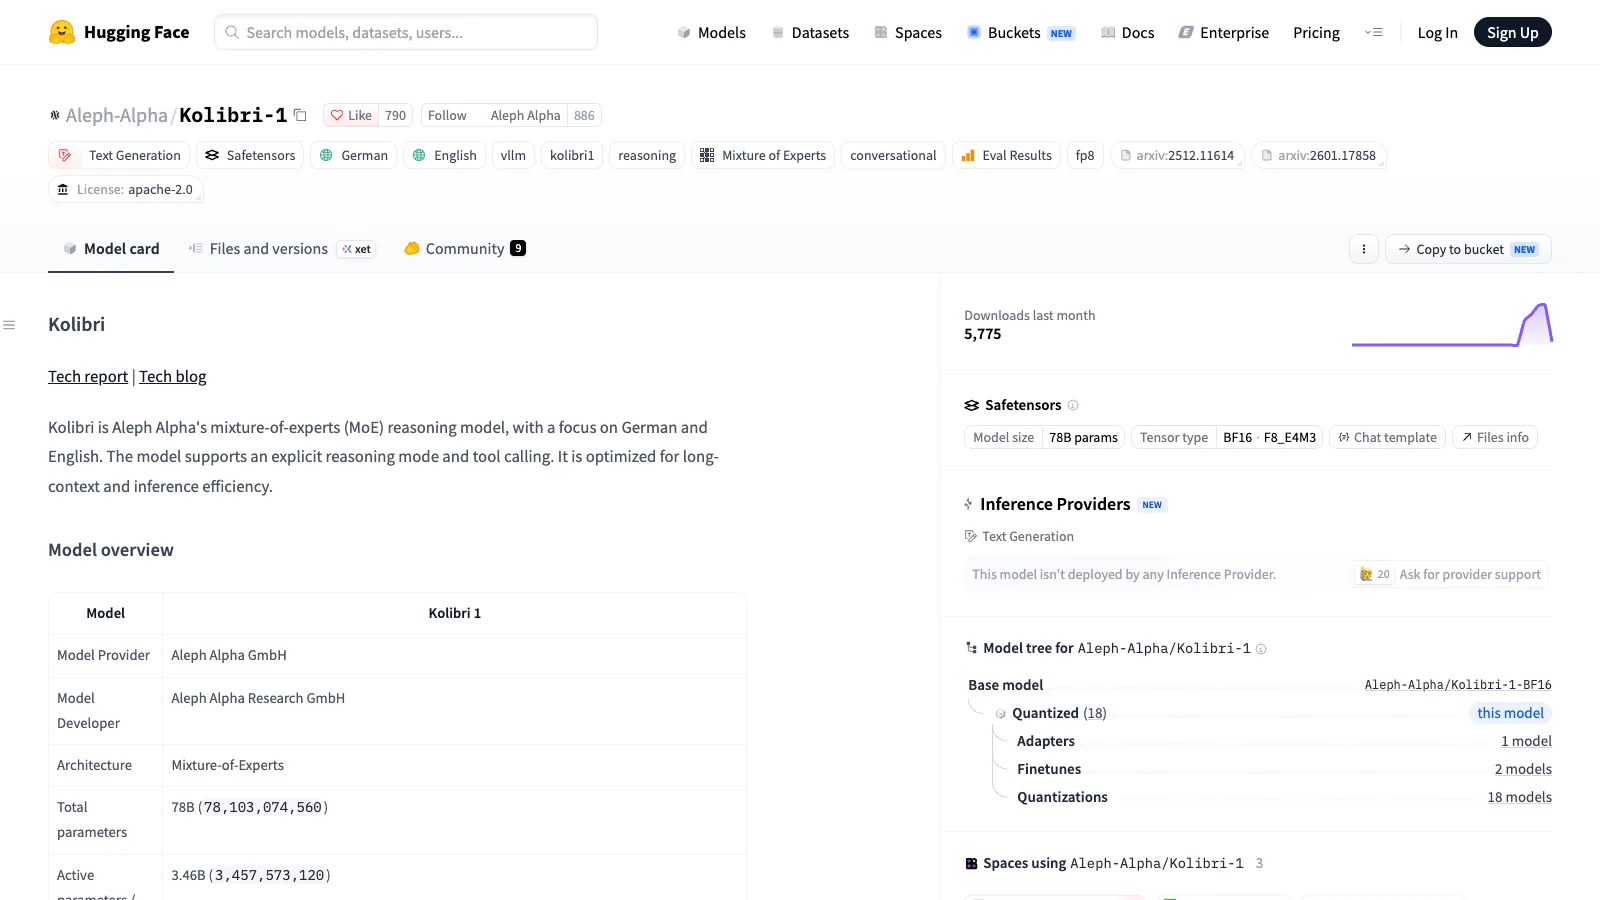
Kolibri-1 is a text AI model from Aleph Alpha, based in Heidelberg, Germany. Its weights are available on Hugging Face. A law firm could serve it on its own infrastructure and analyse documents without sending them to an external AI service. Local hosting alone does not guarantee privacy compliance: secure access, retention and review still matter.
Open weights under Apache 2.0 permit commercial use and adaptation in your product. The grant covers published weights and configuration, not the training code. Released on 3 October 2026, this is a German and English text model, not a Portuguese or image model.
Think of a hospital with 384 specialists on each floor: for each word, 6 are called in and 1 shared specialist always participates. This mixture of experts repeats across 50 layers for each token. Of 78.1 billion parameters in total, about 3.46 billion are active per token. You still need memory for all the weights.
Do you have the hardware?
| Machine | Route as of 8 October 2026 |
|---|---|
| GPU server | Official FP8 weights occupy roughly 78 GB; minimum 1 H200/B200/B300 or 2 A100 80 GB / H100 SXM5 GPUs. |
| 64 GB Apple Silicon Mac | Unofficial 4-bit MLX conversion, roughly 41 GiB on disk; its author reports 44–48 GB peak depending on prompt length. |
| 48 GB / 36 GB Mac | Unofficial 3-bit / 2-bit conversion, respectively; more quality loss. Not covered in these steps. |
| Ordinary laptop / 16–32 GB | Do not expect useful local inference with this model. Choose a smaller model or a GPU server. |
We could not test on a 64 GB Mac: our machine has 16 GB. There are no installation, answer, Activity Monitor or tokens-per-second screenshots from us. The commands below are from the community conversion's documentation and require manual hardware validation.
Install on a 64 GB Mac (documented, not tested by us)
On a 64 GB Apple Silicon Mac with Python 3 and more than 41 GiB free disk space, create an environment:
python3 -m venv kolibri-env && source kolibri-env/bin/activateInstall the dependencies and record your version. No mlx-lm version has been validated by us; this installs the current available release:
python -m pip install -U mlx-lm huggingface_hubpython -m pip show mlx-lmDownload velaia's 4-bit conversion and its bundled launcher. Review community code before running it; Aleph Alpha does not publish or endorse this conversion:
hf download velaia/Kolibri-1-MLX-4bit --local-dir Kolibri-1-MLX-4bitDo not assume stock mlx_lm.generate supports kolibri1: this conversion needs its bundled run.py and kolibri1.py until architecture support ships upstream. Quantisation can change answer quality.
Ask your first question offline (not tested by us)
With your download complete and environment active, copy the entire command:
python Kolibri-1-MLX-4bit/run.py generate --model Kolibri-1-MLX-4bit --prompt "Explain briefly the difference between weather and climate." --chat-template-config '{"reasoning_effort": "low"}' --temp 1.0 --top-p 0.97 --top-k 128 --max-tokens 1024Check the answer yourself; we do not show invented output. Then switch Wi-Fi off in macOS, verify you are disconnected, and repeat the same command. If it tries to fetch more files, reconnect, finish downloading and retry. Activity Monitor's Memory tab shows real usage on your Mac. We have not measured speed or memory usage ourselves.
For companies: your own GPU server (official route; not tested by us)
Aleph Alpha documents aleph-alpha-inference, which installs its vLLM plugin and exposes an OpenAI-compatible API. On suitable GPU hardware, install and serve:
python -m pip install "aleph-alpha-inference>=1.0"vllm serve Aleph-Alpha/Kolibri-1 --kv-cache-dtype fp8 --reasoning-parser kolibri1 --tool-call-parser kolibri1 --enable-auto-tool-choiceIts alternative container is ghcr.io/aleph-alpha/aleph-alpha-inference. Recommended sampling is temperature 1.0, top_p 0.97 and top_k 128. Native training context is 262,144 tokens; quality was validated up to 1,048,576, but Aleph Alpha recommends at most 262,144 for complex work and serving efficiency. A large window does not guarantee perfect recall and uses more memory.
FAQ
Is it free? As of 8 October 2026, published weights and configuration carry an Apache 2.0 licence without a licence fee. Hardware, power and operations cost money; verify current hardware prices with the seller.
Does it speak Portuguese? Not as a declared target language. The card lists German and English. Fine-tuning is permitted by the licence but does not guarantee Portuguese quality.
Does it work in Ollama or LM Studio? Do not assume it does. As of 8 October 2026 the documented routes are vLLM with Aleph Alpha's plugin or community MLX with its launcher. We have not validated a one-click install in either app.
Can I put it in my product? Yes, Apache 2.0 weights permit commercial use, subject to licence conditions and responsible-use guidance. Data stays in-house only if your actual deployment does not forward prompts to a third party.
Has Cohere acquired Aleph Alpha? The companies announced an agreement on 16 September 2026. Regulatory approval was still pending as of 8 October 2026; do not treat the merger as completed.
Sources: official model card, community conversion, launch and vLLM commands and Cohere agreement.
Comments
Have a question or something to add? Join the conversation.
No account needed. Select Sign in and choose a name to comment.
Loading the conversation…
Comment privacyCommenting guidelines